AI DEV RADAR
google/embeddinggemma-2 · Hugging Face
EmbeddingGemma 2 is an open multimodal embedding model built by Google DeepMind which maps text (incl. code), images, video, and audio inputs—and combinations thereof—into a single, unified 768-dimensional vector space. The model has 740M total parameters, combining a 270M parameter text model with
"I'm just a meat proxy hitting 'Enter' for Claude"
I hear this a lot lately, but let's discuss about what that "Enter" button actually represents. If that code breaks the system, leaks user data, or violates compliance, Anthropic isn't going to jail. You are! You aren't just an automated clicker, you are the final who decides t
Woman used claude as her diary - and got reported to the police for contents of her diary
  submitted by   /u/Timely_Impression_92 [link]   [comments]
[Paper] FactorEngram: Factorized N-gram Memory with Basis-Level Gating for Language Models
Lookup-based memory has been a promising way to scale the parameters of large language models (LLMs). It retrieves learned representations of local token patterns, such as n-grams, instead of reconstructing them through successive layers of computation. However, existing designs such as Engram treat
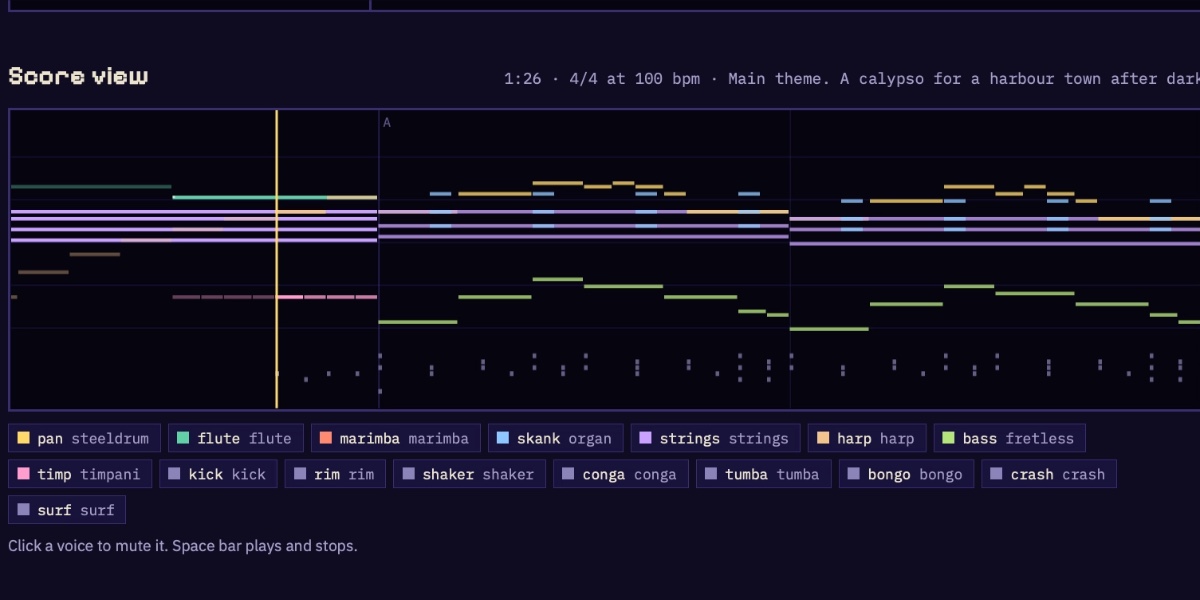
Scrimshaw Jukebox
Tool: Scrimshaw Jukebox I wanted to see if Claude Opus 5.5 could compose music, so I tried this: I want you to write some computer game music for me. First design simple text based format for the music and build an artifact that can play it out loud - include some example tracks in that artifact I a
Qwen3.8-Flash-Next on Strata
Hey! 👋 I have released an official support for Strix Halo machines on Strata for Qwen3.8-Flash-Next. Currently numbers are the best on long context decode and ppts using typical Unsloth’s Q4 and GSQ-RCO model weights. Can go up to 1M context length without big speed loss. Currently support is marke
I gave the 9 most popular Claude Code skills a sugar pill. 2 beat it, 1 did worse than the pill.
Cost with each skill vs its same-length placebo (95% CI). Below 1 = the skill is cheaper. planning-with-files is \"worse\" on pass rate: 80% vs 100%. A skill is just text that lands in Claude's context. Extra text on its own can change how the agent works, so "skill vs
Claude loves ChatGPT sites
So I published an artifact via Claude a few days ago and closed that session. Now that I asked to Claude to put a few changes there - Claude told me he can’t do it because he lacks necessary instruments and suggest SURPRISE to use ChatGPT sites so it won’t happen again lol. Good to see models aren’t
Q (@qtnx_) on X - Mistral Large 4 is still doing RL runs, keep seeing improvements (vs preview version). Release at the end of the month
  submitted by   /u/DerpSenpai [link]   [comments]
[Paper] WaveFront Decoding: Parallelized Self-Speculative Decoding for Looped Language Models
Looped language models repeatedly apply a weight-shared block to increase effective depth without increasing parameter count, but the resulting T sequential recurrent-block calls per generated token substantially increase decoding latency. To address the issue, we introduce Wavefront Decoding (WFD),