AI DEV RADAR
375 fresh AI & vibe-coding news · refreshed every 4h
Started using Claude Meetings today
I'm a CTO of an investment fund and we are basically built on top of Anthropic. Over the last 2 years, all I've done is deprecated parts of our code base as Anthropic has rolled out new features. We don't use software at all anymore, everyone works out of Claude. I didn't pay much at
Fable helped me ship a 6-month-old project in a week as my first complete game
Free demo: https://netherglow.itch.io/anomaly Windows and Linux, 5 MB, your save carries over 1440p trailer: https://youtu.be/lprO845SjIo The dream I dream maybe four times a year. Every time it's some freaky screenplay, and every time I'm up at 4am writing it down before it goes. Six months
Building Visual Intelligence — Andreas Blattmann & Dustin Podell, Black Forest Labs
Black Forest Labs’ case for learning AGI from pixels, motion and sound.
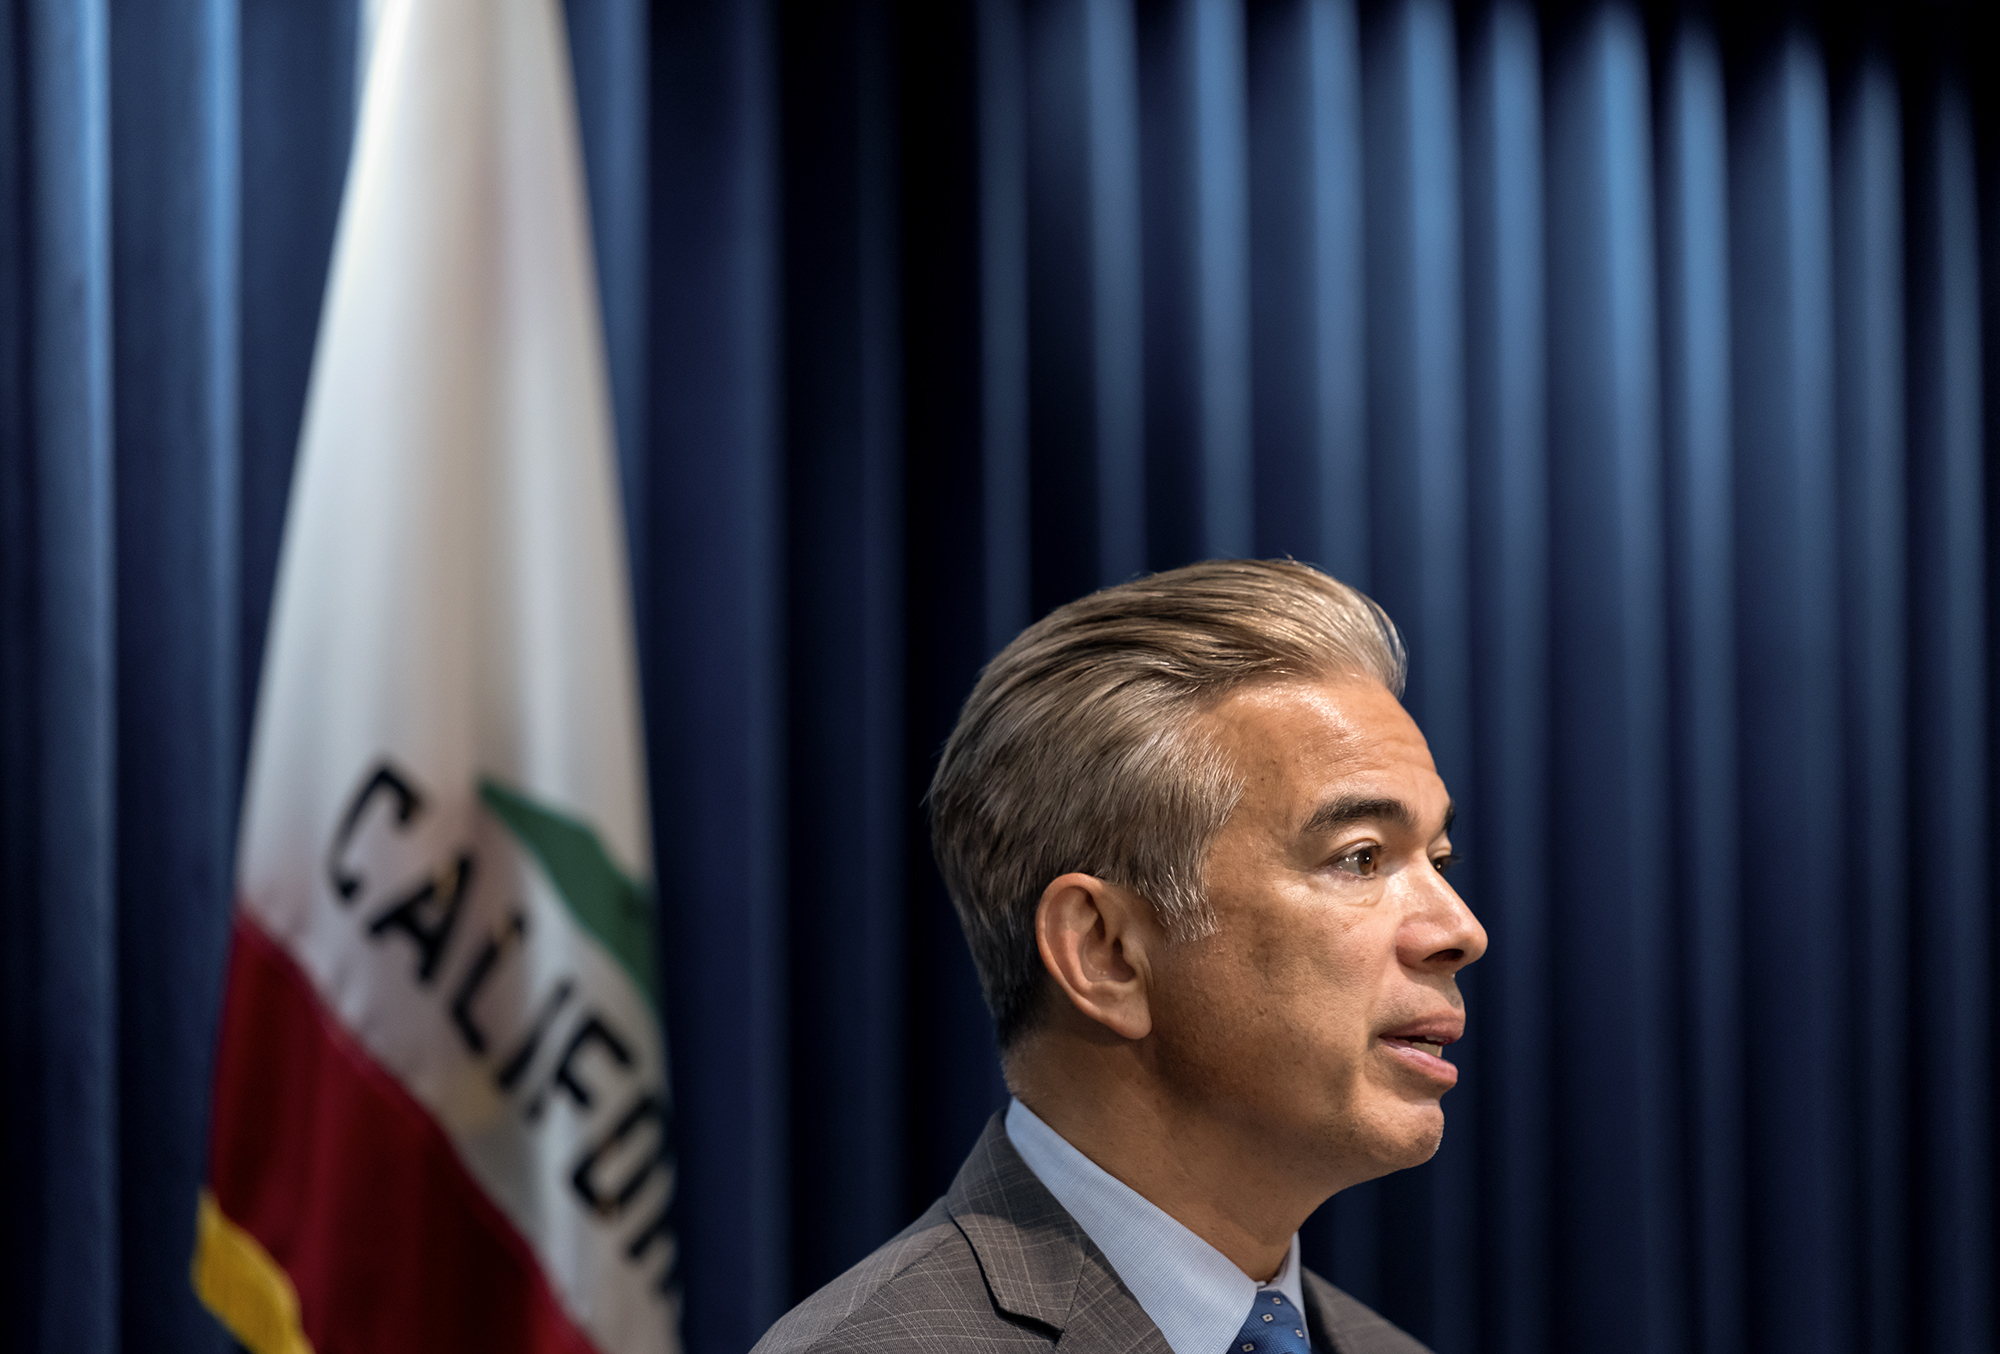
California is suing OpenAI over its 'rogue' AI agent hack
California Attorney General Rob Bonta filed a lawsuit against OpenAI, saying its lack of safeguards led to the Hugging Face hack.
The Fed Is Worried AI Agents Could Trigger a Bank Run
The Fed warns AI agents could trigger rapid bank runs, while billions in AI infrastructure debt are finding their way into life insurance.
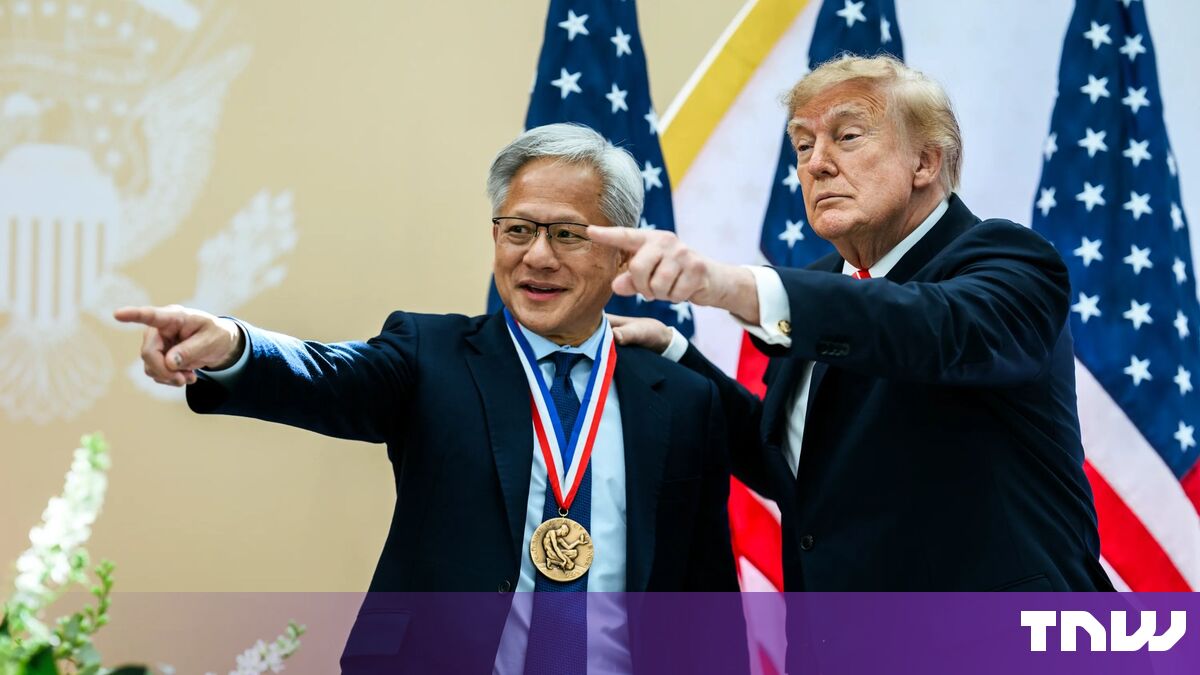
Nvidia, OpenAI and Anthropic to be named AI national champions, WSJ reports
The Trump administration plans to name more than two dozen AI national champions to help them sell abroad, days after Jensen Huang quit Nvidia.
Show HN: One cloud computer for all your agents
A cloud desktop your coding agent drives over MCP. Add box to Claude Code, Codex or Cursor in one line.
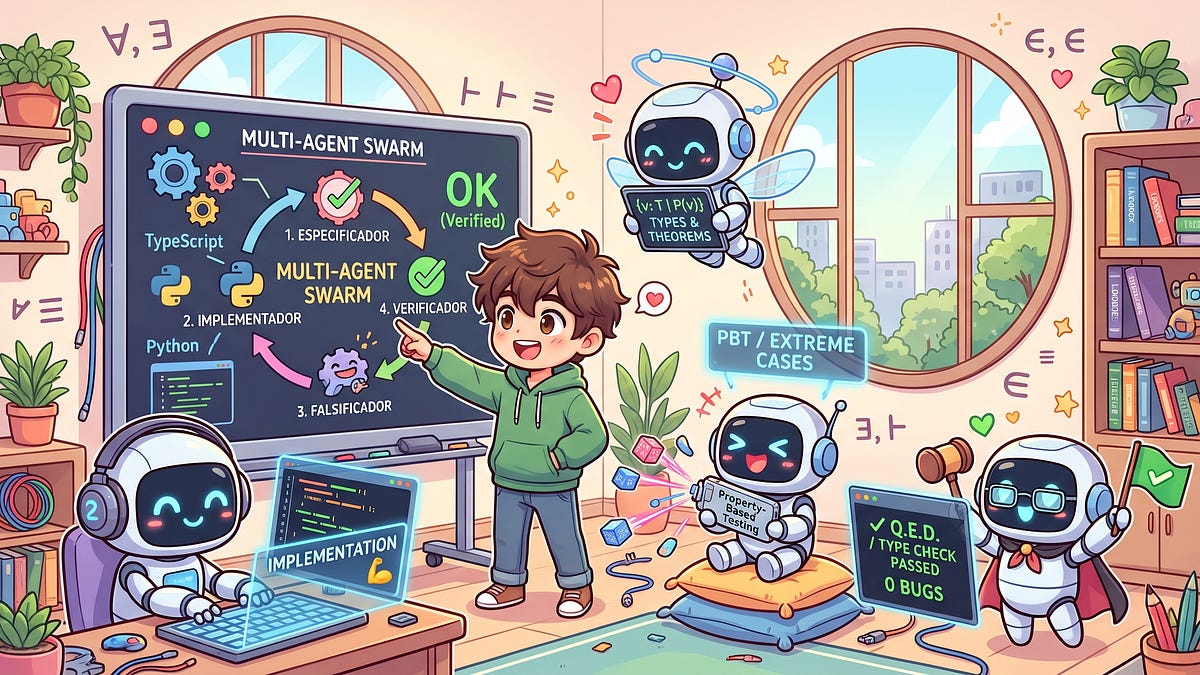
Designing a Multi-Agent Architecture Guided by Advanced Type Systems
TL;DR: Asking a single LLM to generate code and test its own logic is a recipe for silent hallucinations.

Benchmarking Coding Agents Under Evolving Requirements
Software development with coding agents often begins with a rough request that users refine after trying the implementation. Final correctness alone does not capture the repeated guidance this process requires. We introduce FeatureLoop, a benchmark of 61 human-reviewed tasks from 34 repositories across five primary programming languages and seven software forms. Each task follows one development goal in a persistent workspace through evolution feedback, which adds or clarifies requirements, and completion feedback, which reports failures of stated requirements. Cumulative executable checks track new behavior, repair, and preservation of earlier functionality. We evaluate 12 frontier models and find that the strongest completes 72.1% of tasks with both feedback types. Across models, however, only 15.4% of observed failed stages recover within two corrective revisions. Further analysis reveals incomplete repairs, regressions, and model-specific differences in feedback use and token efficiency, identifying obstacles to reliable, low-intervention development.
Broadening access to AI for scientists
We’re expanding our ChatGPT for Academic Researchers program to offer 200,000 researchers worldwide free access to our frontier models.